 lefteros
LEFTEROS / PERSONAL NOTES
A model of my own on Hugging Face: RecMeets' Laya
29 September 2026 / Lefteris Iliadis / SomniusX
I’ve published on Hugging Face the first model I trained for RecMeets: somniusx/recmeets-laya-words. It does one thing and does it well: it reads a word in its sentence, as a speech recognizer wrote it, and says how likely it is that the word was misheard. In Greek and English.
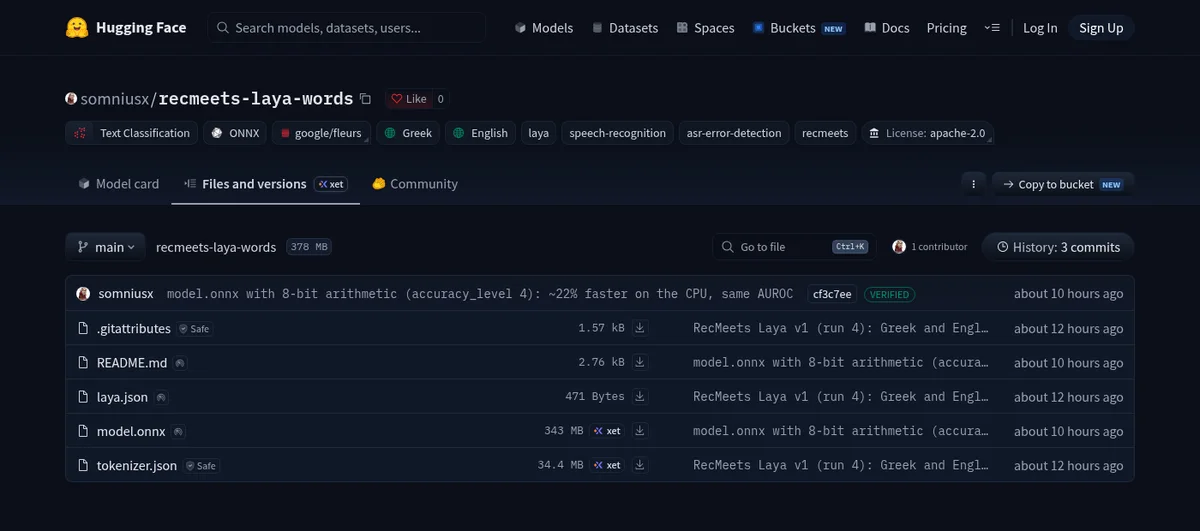 It is a fine-tune of Laya, a multilingual decision model, and I trained it on my own computer, with an RTX 4080 SUPER, on real Whisper mistakes in Greek and English speech. Its Hugging Face page holds its description, the data and the results, and the files you need to run it: the model in ONNX (343 MB), the tokenizer and a settings file. It runs on the processor, with no graphics card and no cloud, and it is open under the Apache 2.0 licence.
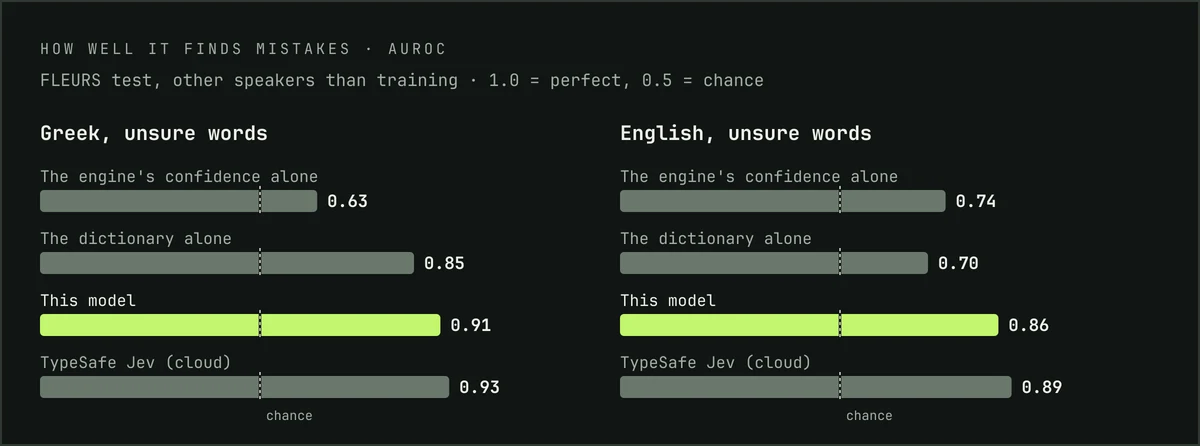
- Greek: AUROC 0.91 on the words the engine is unsure of, where its confidence alone reaches just 0.63.
- English: 0.86 on the same kind of words.
- Close to the cloud: TypeSafe’s Jev, in the cloud, scores 0.93 and 0.89. Mine is free and runs locally.
Along the way I found and fixed four problems in RecMeets itself, from Whisper loops to quiet voices that were being lost. And the model isn’t finished: I keep improving it.
The whole story, the data, the training, the computer, the numbers and how to use it in your own projects are on the RecMeets' Laya page.